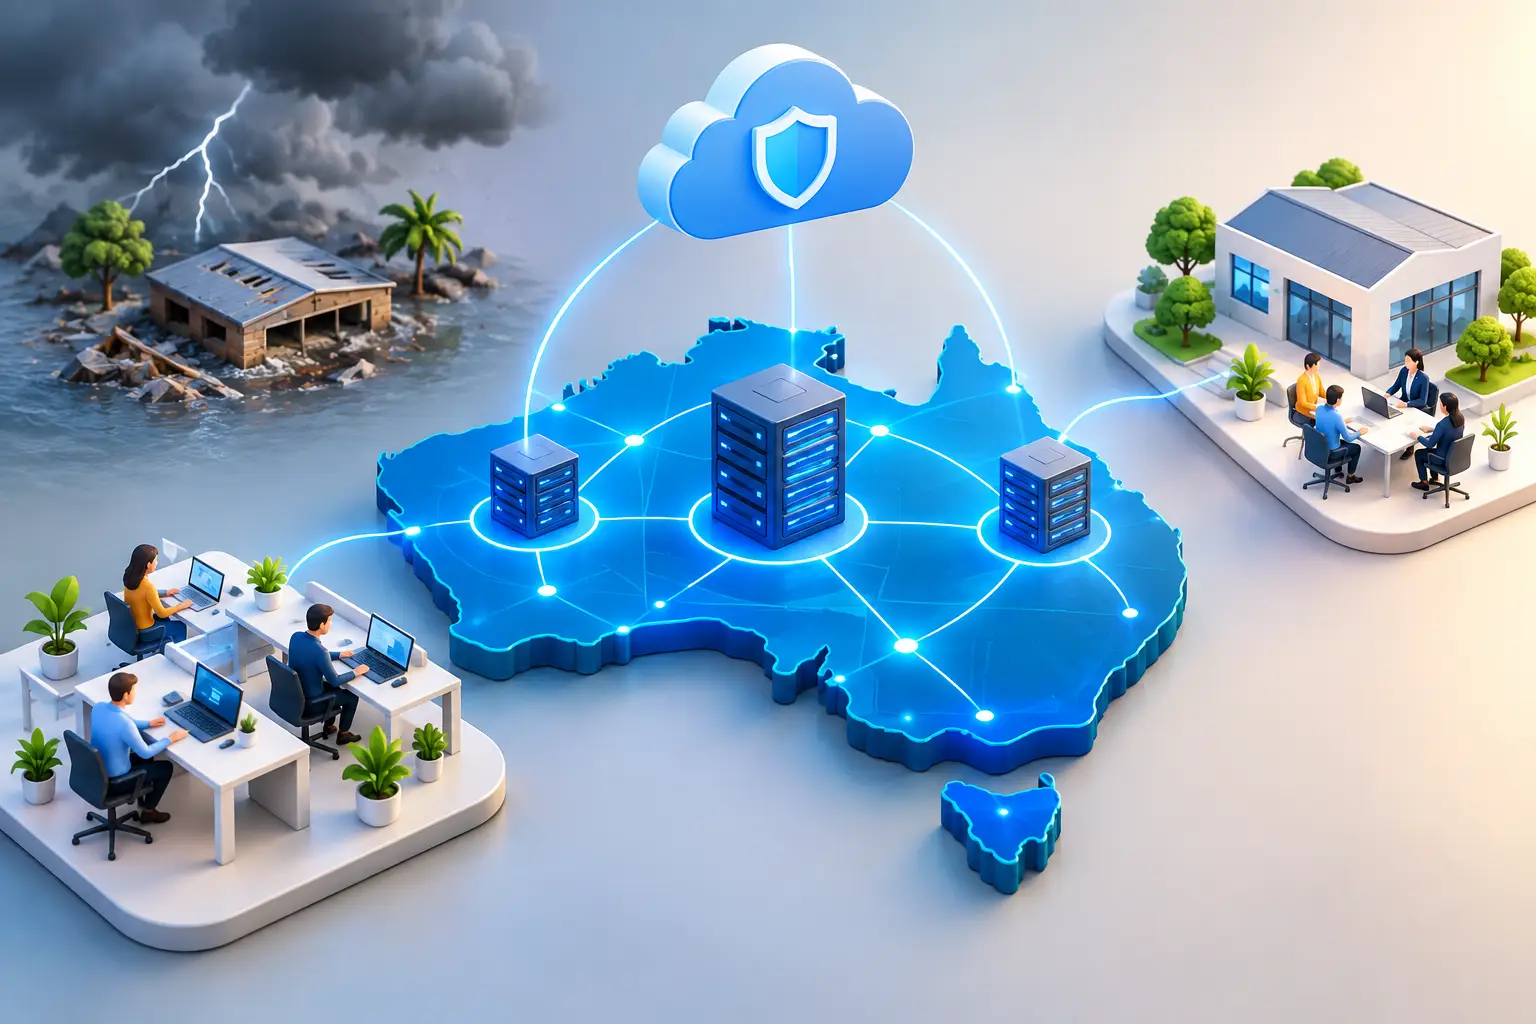
A power fault takes an office offline at 10:15 am. Staff cannot access files, customers cannot reach the main number and cloud applications begin timing out. A useful disaster recovery network example shows what should happen next: internet traffic moves to a backup connection, phone calls redirect, priority systems remain available and staff can keep working from another location.
For Australian businesses, disaster recovery is not just about recovering a server after a major incident. It is about keeping communications and essential systems available through the more common disruptions: a damaged fibre lead, NBN outage, construction works, equipment failure, bushfire risk, flooding or a local power problem. The right design depends on what your team needs to keep operating and how long the business can reasonably tolerate an interruption.
A practical disaster recovery network example
Consider a 45-person accounting firm with one main office in Melbourne, a smaller regional office and staff who work from home during peak periods. The business uses cloud accounting software, Microsoft 365, a cloud PBX, shared documents and a line-of-business application hosted in a private cloud environment. Its reception number is critical during tax time.
At the main office, the primary connection is business-grade fibre or Enterprise Ethernet, chosen for consistent performance and service assurances. A second connection uses a different access method, such as NBN business broadband, fixed wireless or 5G. Both services connect to a managed firewall or SD-WAN appliance.
This detail matters. Two services from the same building entry point or relying on the same upstream infrastructure may not protect the business from the same physical fault. True resilience comes from reducing shared points of failure where practical. For a site with high call volumes or revenue-sensitive systems, the secondary connection should ideally take a different network path and use separate equipment.
The firewall continually checks the primary connection by sending traffic tests to more than one destination. If it detects a sustained failure, it automatically directs internet traffic through the backup service. Staff may notice slower performance on large uploads, but email, cloud applications, payments and remote access continue to function.
The cloud PBX is configured with a continuity rule. If desk phones at the office are unavailable, incoming calls can ring mobiles, a regional office queue or remote staff. Calls should not simply disappear because the office internet connection has failed.
The accounting firm also has encrypted backups of its critical private-cloud data stored in a separate Australian location. If the primary hosted environment becomes unavailable, the business can restore systems to a recovery environment. This is different from internet failover: one protects connectivity, while the other protects applications and data.
What the design looks like in practice
The recovery path is straightforward:
- Primary fibre carries normal office traffic.
- A firewall or SD-WAN service monitors the fibre connection.
- A separate NBN, fixed wireless or 5G service takes over when the primary service fails.
- Cloud phone calls redirect to nominated staff or another site.
- Secure remote access lets priority staff work from home or a temporary location.
- Backups and recovery systems protect data if the issue affects more than the local network.
The purpose is not to make every system identical during an outage. It is to preserve the work that matters most. The business may pause large software updates and non-essential guest Wi-Fi while keeping customer calls, secure cloud access and payroll systems running.
Start with recovery targets, not equipment
A second internet service is valuable, but it is only one part of a workable plan. Before selecting connections or hardware, define two practical targets.
The recovery time objective, or RTO, is how quickly a service must be available again. For example, a customer-facing phone system might need to recover within minutes, while an archive system could wait until the next business day.
The recovery point objective, or RPO, is how much data the business can afford to lose. If the RPO is one hour, backups or replication need to capture changes at least every hour. A nightly backup does not meet that target for a system processing orders all day.
These targets help avoid spending heavily on protection for low-priority systems while under-protecting the services that actually keep revenue moving. A regional medical practice, for instance, may prioritise phone diversion and secure access to appointments. A multi-site wholesaler may place greater priority on warehouse connectivity, EFTPOS and stock systems.
Choosing the right backup connection
There is no single best secondary service for every site. The choice comes down to availability, traffic needs, location and the risk being addressed.
NBN business broadband can be a sensible secondary path where it uses infrastructure separate from the primary service. It is cost-effective for many offices and suits general cloud traffic. Fixed wireless or 5G can provide valuable diversity because it does not rely on the same local cable path. Its performance can vary according to signal, local congestion and building position, so it should be tested before being treated as the only backup.
Satellite may be the practical option for remote and regional locations where terrestrial services are limited. It can maintain critical communications and cloud access, though latency and weather conditions can affect certain applications. Private fibre and Enterprise Ethernet are often appropriate where uptime, capacity and predictable performance are central to the operation.
For a small business, an automatic 4G or 5G failover service may be enough to keep cloud software and phones running during a short outage. For an enterprise site, two independently delivered high-capacity services, managed firewalls and SD-WAN policies may be justified. The difference is not company size alone. It is the cost of downtime.
Make phones part of the recovery plan
Phone continuity is frequently overlooked until the main office cannot answer calls. A disaster recovery plan should specify where each inbound number goes when the normal site is unavailable, who can change that rule and how staff will know it has activated.
Cloud PBX systems are particularly useful because users can answer calls through a mobile, softphone or another desk handset. However, the plan still needs to account for mobile coverage, headset availability, call queue messages and after-hours routing. If reception staff are unable to access the building, a pre-set diversion to another team member can protect customer service immediately.
Test outbound calling as well. Some systems can receive redirected calls but need the correct configuration to present the business number when staff call customers back.
Security cannot be switched off during an outage
A common mistake is creating an emergency workaround that bypasses normal security controls. Staff may be tempted to use personal email, uncontrolled file-sharing tools or open remote access when the office is unavailable. That can turn a connectivity incident into a data breach.
Keep the recovery design secure by using managed firewalls, multi-factor authentication, encrypted VPN or zero-trust access, endpoint protection and clear permissions for administrators. Backup connections should follow the same filtering and monitoring policies as the primary connection. Remote workers need a documented process for accessing systems safely, not an improvised one sent through a group chat.
For higher-risk organisations, segment the network so guest devices, cameras, building systems and general office traffic cannot interfere with critical services. SD-WAN can help apply these priorities automatically, directing essential applications through the best available path while limiting lower-priority traffic on failover links.
Test the plan when nothing is wrong
A recovery plan that has never been tested is an assumption, not a capability. Schedule a controlled failover test at least twice a year and after meaningful network changes. Disconnect the primary connection in a planned window, confirm the backup path activates and check the systems staff actually use.
Test more than internet browsing. Place inbound and outbound calls, access cloud applications, process a payment if relevant, connect remote users and verify alerts reach the right people. Record how long each step takes and fix the gaps. A failed test is useful when it happens on a quiet afternoon rather than during an outage.
Document the essentials in plain language: service account details, escalation contacts, hardware locations, who can approve changes and the order in which systems should be restored. Keep a protected copy accessible even if the office network is down.
InfiNET Broadband can help businesses assess available primary and backup connectivity options, then align them with managed networking, cloud voice and security requirements. The goal is practical continuity: your people know what to do, customers can still reach you and the business has a clear path forward when the unexpected happens.